tech
NVIDIA Explains How Its GPUs Accelerate OpenAI's GPT-6 Astra
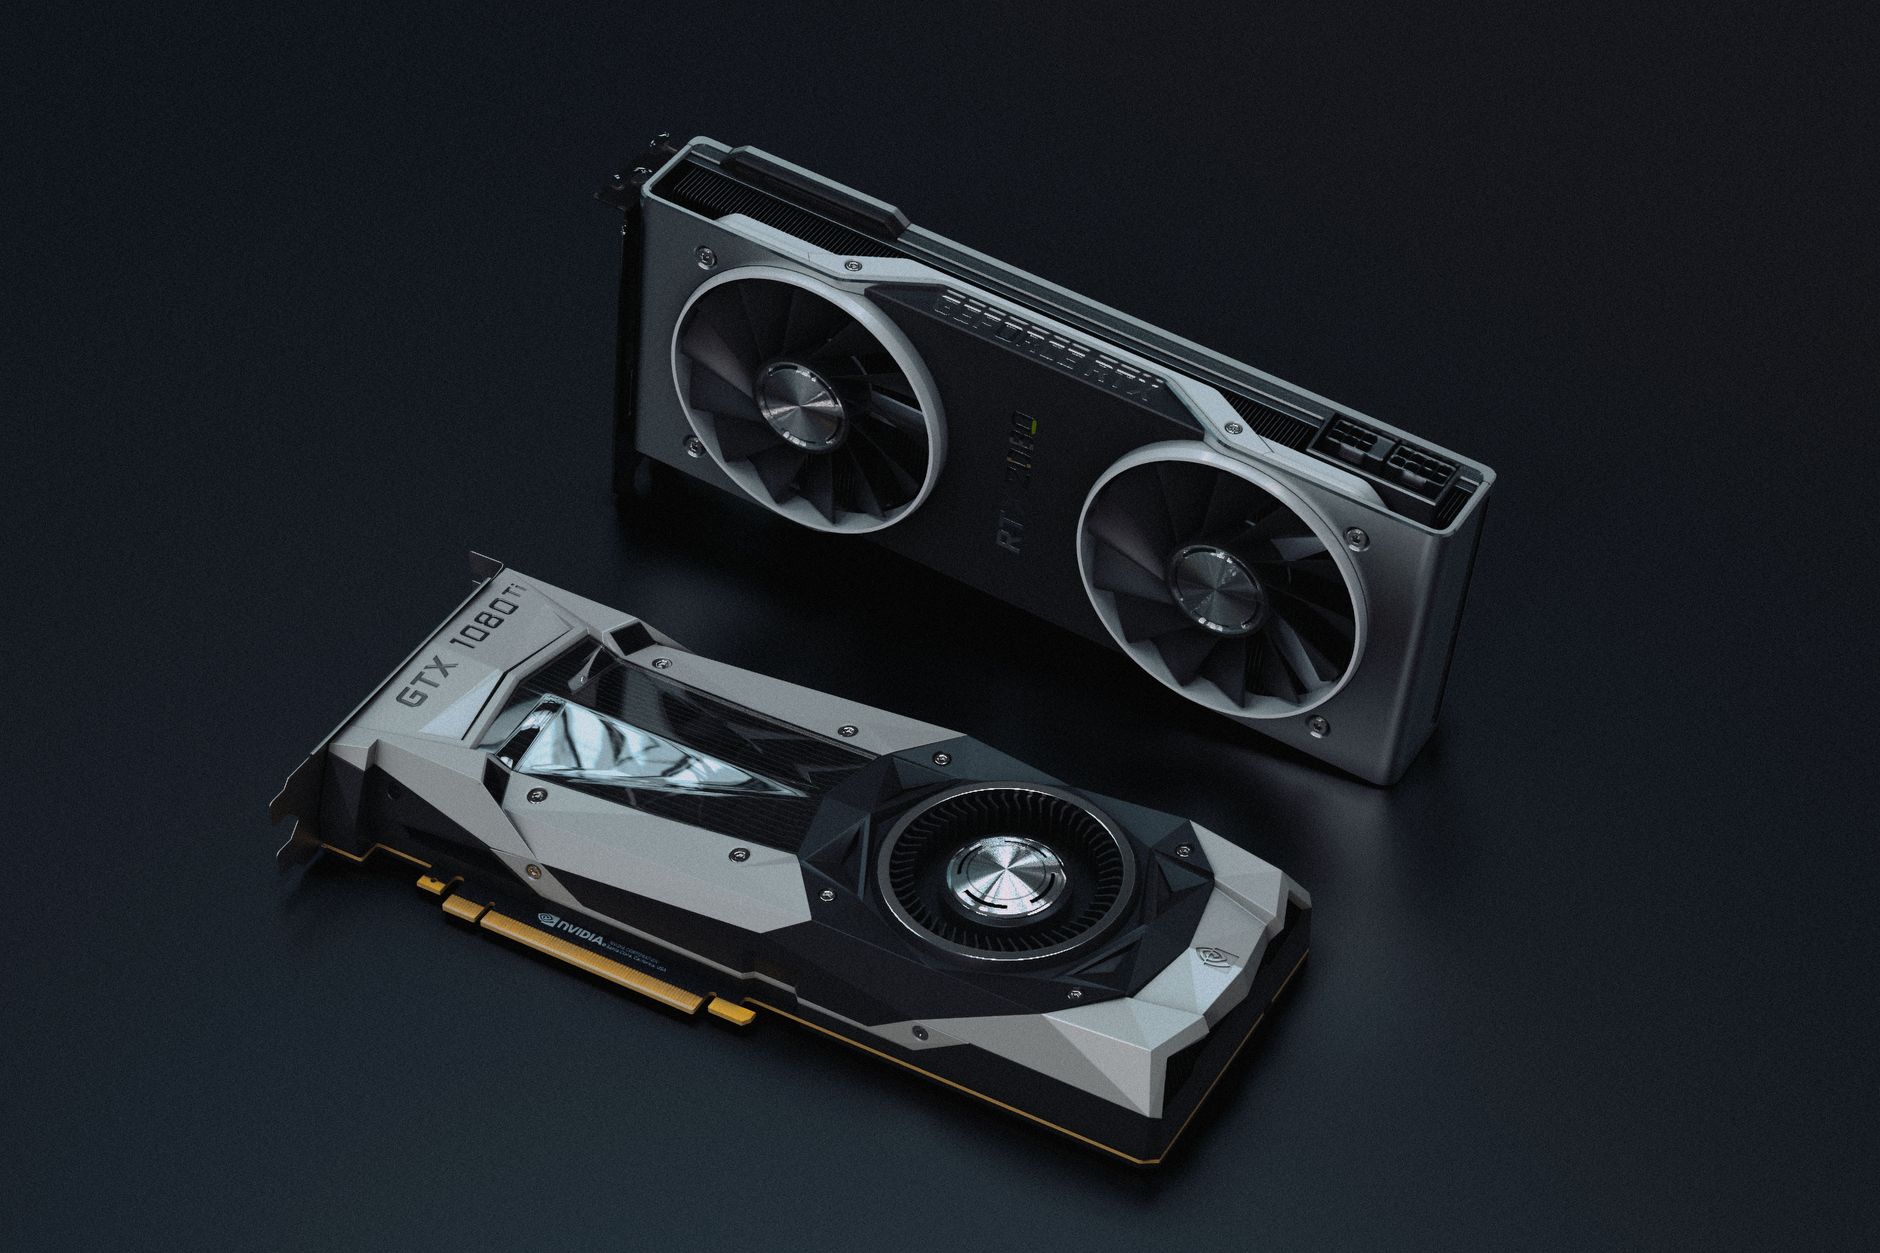
NVIDIA's company blog published a post titled "How NVIDIA GPUs Help Accelerate OpenAI's GPT-6 Astra Ultrafast," confirming the chipmaker is positioning its hardware as the compute layer behind a model OpenAI is calling GPT-6 Astra, according to the post as indexed by Google News. The headline is the only confirmed detail available at publication time; the full post's benchmark figures were not accessible for review.
What does NVIDIA's blog say about GPT-6 Astra?
The title alone establishes two facts: NVIDIA GPUs are described as the acceleration layer for the workload, and OpenAI has attached the internal name "Astra" to a GPT-6-branded model with an "Ultrafast" designation. No chip generation, cluster size, token-per-second rate, or training-versus-inference distinction appears in the headline itself, and HTT News could not independently verify additional specifics from NVIDIA's blog at the time of this report.
What hardware is involved in the acceleration?
NVIDIA's blog network has historically used posts like this to spotlight specific GPU families, interconnects, or software stacks tied to a named customer deployment. The GPT-6 Astra post follows that naming convention, but the source material reviewed here does not specify which GPU architecture, how many units, or what networking fabric is involved. Any claim about specific hardware configurations would go beyond what has been confirmed and is omitted here.
Why are performance numbers missing from the announcement?
Company blog posts tied to a single customer frequently precede a fuller technical disclosure, such as a developer conference keynote or a joint technical paper. As of this report, no throughput figures, latency numbers, or cost-per-token data tied to GPT-6 Astra have been verified in public source material. That absence is itself the most reportable data point right now: zero of the figures a reader would expect in a GPU-performance story — FLOPS, GPU count, power draw, cost — have been corroborated.
How should readers interpret the "Ultrafast" label?
"Ultrafast" appears only in the headline, with no accompanying metric defining what it measures against. Readers should treat it as a marketing descriptor until NVIDIA or OpenAI attaches a number — a specific inference speed, time-to-first-token figure, or comparison to a prior model — to the term.
What should readers watch for next?
- Whether NVIDIA's full blog post, once reviewed, discloses a specific GPU model (such as a named architecture or chip tier) tied to GPT-6 Astra.
- Whether OpenAI issues its own technical note or system card referencing "Astra" by name.
- Whether either company publishes a benchmark, such as tokens-per-second or training-cluster size, that can be independently verified.
- Whether the "Ultrafast" designation reappears in OpenAI product documentation with a defined meaning.
Glossary
- GPU (graphics processing unit): A chip originally built for rendering graphics, now used to run the parallel math behind large AI models.
- Inference: The process of running a trained AI model to produce an answer, as opposed to training it on new data.
- Throughput: How much work a system completes in a given time, often measured in tokens generated per second for language models.
- System card: A technical document companies like OpenAI sometimes publish alongside a model release, describing its capabilities and limitations.
HTT News will update this report if NVIDIA's full post or an OpenAI statement discloses specific figures tied to GPT-6 Astra.
mindfulAI Keyboard — An iPhone keyboard that rewrites a draft in a tone you pick. Four free AI actions a day.
Questions
What is GPT-6 Astra?
It is the name used in NVIDIA's blog headline for an OpenAI model that NVIDIA says its GPUs help accelerate; no further technical description has been independently verified.
Has NVIDIA released specific performance numbers for GPT-6 Astra?
No chip counts, throughput, or latency figures tied to GPT-6 Astra were confirmed in available source material as of this report.